AI Driver
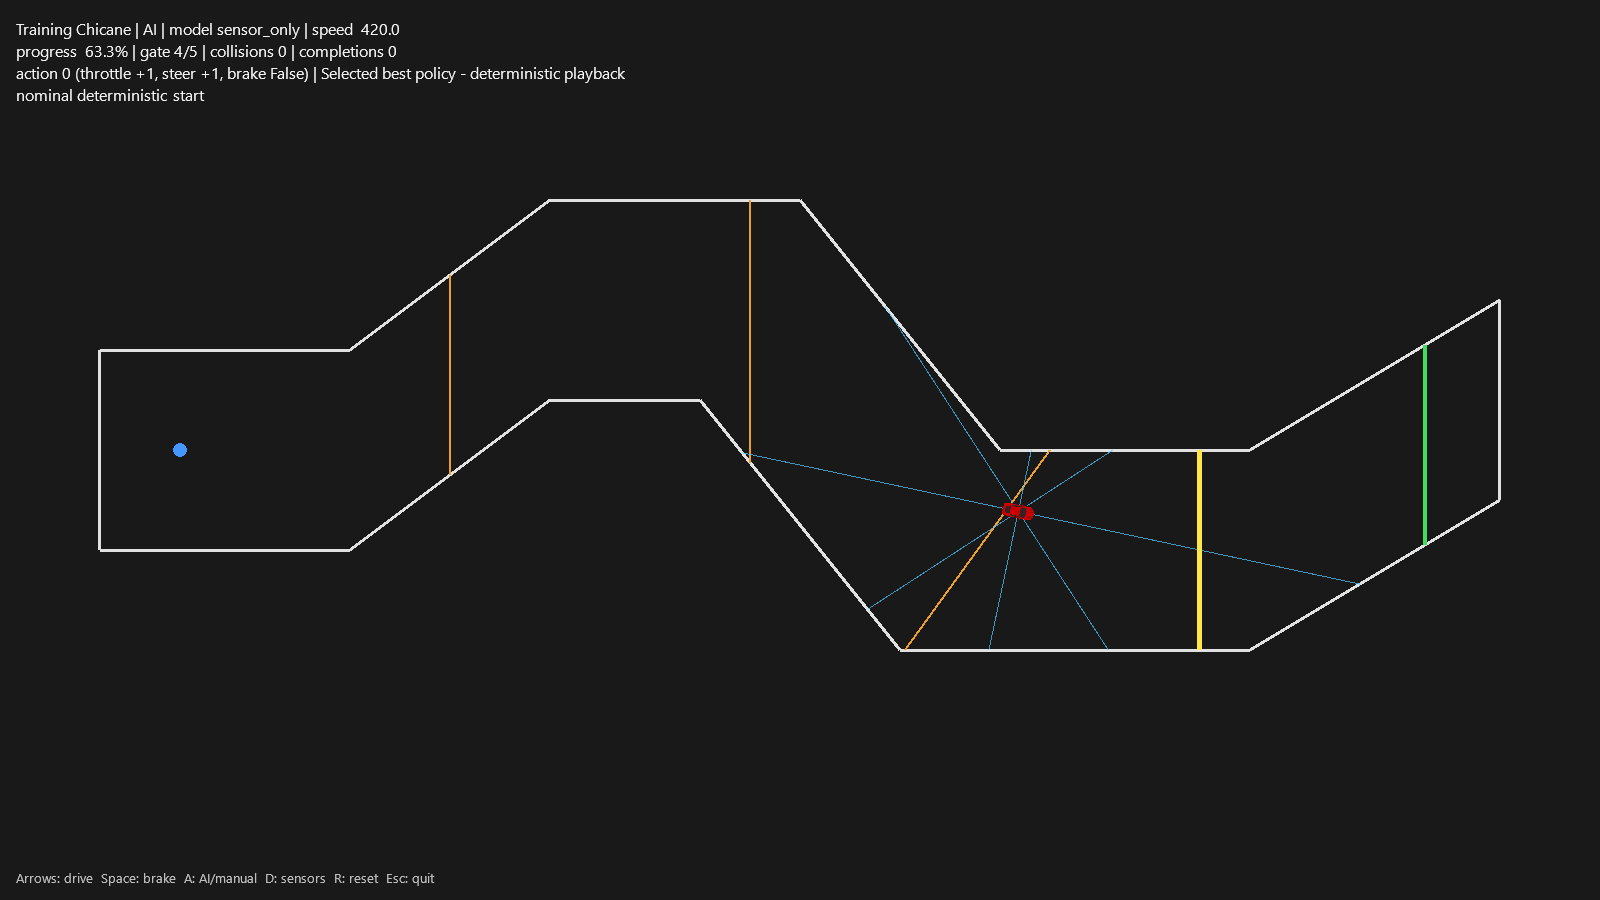
A driving simulator and controlled reinforcement-learning experiment exploring how observation design affects a learned policy.
- contribution
- Independent simulation, learning pipeline, and experiment development
- stack
- Python, TensorFlow / Keras, DQN, NumPy, Pyglet
- status
- Completed local experiment with authentic trained-policy playback, reproducible reports, and documented generalization limits.
From simulation to a controlled comparison
I built the driving environment, ray sensors, collision handling, training workflow, and interactive playback. Separating simulation from rendering made the same vehicle behavior usable for manual driving, headless training, and deterministic evaluation.
The experiment compared sensor-only and track-aware observations under equal training budgets: three seeds per variant, six runs, and 12,000 logical training episodes. Resumable and validation-selected checkpoints served different purposes, while a protected blind circuit stayed outside training and model selection.
What the result showed
Both variants mastered the nominal training layouts. Sensor-only observations transferred better to the development layouts in this experiment, while neither variant completed the blind circuit.
GitHub holds the implementation, authentic playback captures, methodology, result tables, and retrospective. Those details explain both the useful result and its limits.